
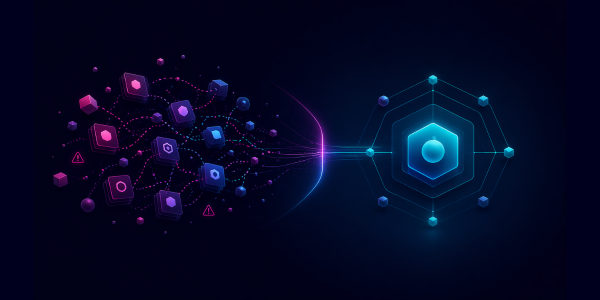

Define
Already happened before this moment, the agent’s persona, its diagnostic tool scope, and its autonomy threshold were set in FlowAgent Builder ahead of time.



This guide breaks down what’s inside Itential’s agent harness: Tools and Skills that give a FlowAgent something to call and expertise to follow, Context that grounds it in real infrastructure state, and Governance that decides what it’s allowed to do.
Learn how a FlowAgent moves from goal to governed action, and get AI’s reasoning without giving a model unsupervised access to production.
Every AI agent is a combination of two things: a model that reasons, and a harness that lets it act. Model capability is converging: multiple vendors now offer models with broadly comparable reasoning ability, and the gap between them narrows with each release. That shifts what actually determines whether an agent works well in production. It’s not which model it runs. It’s what’s built around it, the tools it can reach, the context it reasons over, and the governance that constrains what it’s allowed to do.
Infrastructure raises the stakes on that governance more than most domains. A mistake here isn’t caught in a code review. It can take down a service or fail an audit in real time. FlowAI is Itential’s answer to that standard: the agent harness of the Itential Platform, built from four components – Tools, Skills, Context, and Governance – that let a FlowAgent reason through a goal and act on real infrastructure under the same governance as every human and every deterministic workflow already running on the platform.
That governance isn’t new. It’s inherited from more than a decade of production automation use across some of the largest network and infrastructure estates in operation, which is also why it’s a different proposition than building the same thing from scratch.
An AI model, on its own, does one thing: it reasons about an input and produces an output, then stops. It doesn’t remember what happened last time, can’t take a next step on its own, and has no built-in sense of a change window, a blast radius, or a compliance requirement.
An agent harness = model + tools + skills + context + governance + the loop that keeps it working. Everything after the model is what turns reasoning into a completed job: tools it’s allowed to call, skills it follows, context it draws on, governance that constrains it, and a loop, observe, reason, act, check, that keeps it going until the task is done.
A harness is not a chatbot, a single screen, or something you install once. It’s tools, skills, context, governance, and a loop, spread across a platform’s execution engine, running underneath every agent built on it.
An agent, in short, is a model plus a harness. Two products can run the identical model and behave completely differently, because the harness, not the model, decides what the agent is actually allowed and able to do.
| Term | What it is |
|---|---|
| Model | The LLM. It reasons about an input and produces an output, then stops. |
| Harness | Everything wrapped around the model, tools, skills, context, governance, and the loop, that lets it act instead of just answer. |
| Agent | One configured instance of a harness: a specific persona, goal, tool scope, and autonomy threshold, set at build time. |
| Workflow | A deterministic sequence of steps that runs the same way every time. An agent can call a workflow as a tool; a workflow doesn’t reason. |
Most agent harnesses break down into four generic parts, regardless of vendor or platform.
Every harness implements these four differently. The rest of this guide covers how FlowAI implements them for infrastructure.
If you’ve built or used a coding agent – Claude Code, Cursor, an internal Devin-style tool – you already know the word ‘harness.’ A coding agent that makes a mistake gets caught in review, reverted, and redeployed. The harnesses built for coding agents were built inside that tolerance, guardrails added where convenient, because the cost of a mistake was a wasted pull request.
Infrastructure doesn’t get that tolerance. A mistake here doesn’t get caught in review. It can take down a service, open a security gap, or fail an audit, in real time, in production.
A harness built to read a file and run a test was never built to know a change window, a blast radius, or a compliance obligation. That’s a different, harder problem, and it’s the one FlowAI was built to solve.
FlowAI is the agent harness of the Itential Platform – tools, skills, context, and governance, working together. A FlowAgent is built in FlowAgent Builder and runs on the platform’s execution engine, with that same harness enforced on every action, whether it came from a FlowAgent or a person.
FlowAI isn’t a separate product added on top of the platform, and it isn’t a model. It’s what a harness looks like when it’s built specifically for infrastructure.
| Term | What it is |
|---|---|
| Harness | Everything wrapped around the model, tools, skills, context, governance, and the loop, that lets it act instead of just answer. |
| FlowAI | Itential’s harness – tools, skills, context, and governance, built specifically for infrastructure. |
| Execution Engine | The runtime that enforces the harness – RBAC, approval gates, pre/post-checks – on every action. |
| FlowAgent Builder | The authoring UI, where an agent’s persona, tool scope, and autonomy threshold get configured. |
| FlowAgent | The result: one configured instance running on the execution engine, built in FlowAgent Builder. |
Each part does a specific job, and each was proven in production before a single FlowAgent existed. The next four sections take them one at a time.
It can suggest an action, but it has nothing to actually carry it out.
Every workflow, golden configuration, lifecycle state, automation, API, and gateway service already on the Itential Platform is registered as a callable tool. A FlowAgent calls these tools with structured inputs and defined outputs. It never touches infrastructure directly.
Effectively everything already running on the Itential Platform is exposable as a tool: every workflow, every Itential Gateway service, including the Python scripts and Ansible playbooks Gateway exposes, every API, and every automation. Nothing needs to be rebuilt or wrapped separately to become callable; if it already runs on the platform, an agent can call it. That includes 1,000+ open source integrations across network, cloud, ITSM, security, and observability systems, a fully documented REST API covering every platform capability, the Itential MCP Server and FlowMCP Gateway for connecting external LLMs, and CLI, Netconf, and RESTCONF connectivity for devices that don’t expose modern APIs. Configuration compliance and drift detection, Golden Configuration templates, and lifecycle state tracking are callable the same way. Existing Ansible playbooks, Python scripts, and OpenTofu plans become callable tools too, no rewrite required.
Some agent architectures let an agent acquire new tools while it’s running. Itential’s harness sanctions tools before deployment instead, so every agent’s boundaries are known before it ever touches production.
It reasons from scratch every time, with no memory of how your team actually handles a given situation.
Skills encode repeatable task expertise as structured instructions. A Skill defines how a network engineer would handle a vulnerability response, an OS upgrade, or a config drift, and a FlowAgent follows that expertise rather than improvising a new approach every time it encounters a similar situation. Skills are what keep a FlowAgent’s behavior consistent across runs, and consistent with how the team already operates.
A DDI engineer’s Skill for allocating IP space looks nothing like a security engineer’s Skill for vulnerability triage, each encodes what that specific role already knows how to do, not a generic instruction set applied across the board.
It reasons over whatever text it’s handed, often stale documentation or an unstructured prompt.
Agents reason over live infrastructure state.
That means real device inventory, real configuration state, and real ticket history, not a snapshot from whenever someone last wrote it down. Grounding reasoning in current state is what keeps an agent’s decisions relevant to what’s actually true right now, rather than what used to be true.
That context is powered by the same systems already tracking that state for deterministic automation: Configuration Manager for compliance posture and drift, Lifecycle Manager for resource and configuration state over time. An agent isn’t querying a separate AI-only data layer. It’s reading the same state your workflows already treat as ground truth. Context reaches the agent through the same read-only tool calls as everything else, live device, config, and ticket state is pulled on demand at reasoning time, never pre-cached or stale.
There’s nothing stopping it from taking an action it was never meant to take.
Governance runs in three layers, configured at build time and enforced by the platform at runtime.
Worth separating two things that get discussed as one: what’s fixed, platform-wide infrastructure you inherit, RBAC model, audit trail, secrets handling, rollback behavior, and what’s configured per agent, persona, tool scope, and autonomy threshold. The first is built once and applies to everything. The second is decided fresh every time someone builds a new FlowAgent.
Every action, agent or human, writes to the same immutable audit trail. Itential holds zero data retention on customer infrastructure data and is SOC 2 Type II by default.
This is also where build-time tool sanctioning and runtime governance meet: the tools an agent can call were fixed before deployment, and every call it makes against that fixed set is what the audit trail, approval gates, and RBAC layers above are actually enforcing.

A FlowAgent moves through five stages every time it runs, all on the same engine, all under the same enforcement.
A ServiceNow incident opens.


An agent cannot self-escalate beyond what was defined in the Define stage. Scope, autonomy, and enforcement are set once, before production, and held constant after.
None of this assumes an agent’s reasoning is always correct. It assumes it doesn’t have to be. Pre-checks catch a bad decision before it reaches infrastructure. Post-checks catch one that got through anyway. Approval gates stop anything above a defined risk threshold before it executes at all. An agent reasoning its way to the wrong conclusion is contained by the same layer that would contain a person doing the same thing, it doesn’t get a wider blast radius just because a model made the call.
FlowAgents run on any LLM: open weight models like NVIDIA Nemotron, Kimi K2, or Llama hosted entirely on infrastructure you control, proprietary models like Claude, ChatGPT, or Gemini, or a custom model built and fine-tuned in-house. The model is a choice made per agent, not a commitment made for the whole platform.
That works because the model was never where the harness’s value lived. Swapping the model behind an existing FlowAgent is a configuration change, not a rebuild, since the governed path underneath it, Itential Gateway, direct API calls, or platform workflows, never depended on which model was doing the reasoning.
This matters most for teams navigating specific regulatory requirements: DORA, PCI DSS, and SOX in financial services, HIPAA in healthcare, FedRAMP or air-gapped environments in the public sector, GDPR and the EU AI Act for carriers.
With FlowAI you can run a model that never leaves your infrastructure for a regulated workload, or a frontier model for harder reasoning tasks – under the same governance either way. Swapping later is a configuration change, not a migration.
FlowAgents are already running across a range of operational patterns. A few representative examples:
Each of these runs through the same execution engine described above, with the same RBAC, approval gates, and audit trail applied regardless of which pattern it is.
Both a chat assistant and a FlowAgent are a model calling tools. Both a coding harness and a FlowAgent plan, call tools, and loop on results. The difference isn’t the loop. It’s what’s scoped, and when.
| Copilot / Chat Assistant ChatGPT, Copilot, a generic assistant wired to MCP tools | Itential FlowAgent Purpose-built agent in the Itential Platform |
|---|---|
| Invoked by a person typing into a chat window | Invoked with specified inputs: API, form, workflow, or schedule |
| General-purpose: any topic, any task, any day | Single use case, single persona, single scope |
| Prompt is written fresh at run time, every time | Prompt, instructions, and reasoning style set at build time |
| Broad toolset that shifts as MCP servers come and go | Tool scope picked at build time; nothing else is discoverable |
| Goal changes with every prompt | Goal is fixed; the agent adapts the path, not the objective |
| Ends in a recommendation a human still has to act on | Ends in a governed execution with an immutable audit trail |
| Coding Harness Claude Code, Cursor, Codex — an agent inside a dev loop | Itential FlowAgent An agent inside a governed orchestration platform |
|---|---|
| A developer supervises and steers every turn | Runs unattended, triggered by a workflow or an API call |
| Works in a repo and a sandbox; mistakes are cheap to undo | Acts on live network and infrastructure; changes are real |
| Open-ended tools: shell, filesystem, anything installable | Fixed registry of approved workflows, APIs, and gateway tools |
| Correctness judged by a human reading the diff | Correctness enforced by pre-checks, post-checks, approval gates |
| Every session is exploratory and one of a kind | Every reasoning step and tool call recorded in the session trace |
| Blast radius stops at a branch | Blast radius is production, so autonomy is bounded at build time |
The reasoning loop looks the same in all three. What’s different is when the scope gets decided. A chat assistant decides scope in the prompt, every time. A coding harness decides it turn by turn, with a person watching. A FlowAgent decides it once, at build time, before it’s ever allowed near production, which is why the harness underneath it, not the model doing the reasoning, is what actually earns your trust.
None of that is available off the shelf, though. If it’s not a chat assistant and it’s not a coding harness, the next question is whether you could just build it yourself.
Itential has run deterministic execution, workflows that perform the same steps the same way every time, for over a decade across some of the largest and most complex network and infrastructure estates in operation. The RBAC model, the audit trail, the secrets handling, the rollback behavior, all of it was proven under real production conditions, at that scale, before FlowAI existed. FlowAI doesn’t build that governance for the first time. It inherits it the moment a FlowAgent takes its first action.
That’s the part worth separating from the pitch: building a harness, in the sense of a loop that calls tools and holds context, is a well-understood engineering problem today. Proving that the governance around it holds up at scale, across a decade of real production incidents, is not something a team can compress into a project timeline. It gets proven the slow way, or it doesn’t get proven at all.
This shows up as two different objections, depending on who’s asking.
A network or infrastructure engineering team usually means: we already have scripts and playbooks that work, why do we need a platform under them.
An AI or platform engineering team usually means something more specific: we can build the agent loop with LangChain, LangChain’s Deep Agents, or Pydantic AI’s harness.
Both are legitimate starting points for the parts that are genuinely reusable. Neither ships with the part that takes the longest to prove out.
| Capability | Building It Yourself | FlowAI |
|---|---|---|
| Agent loop, tool-calling | Frameworks like LangChain or Deep Agents get you here | Included, wired into the platform’s execution engine |
| RBAC across build and execution | Custom-built, typically months of engineering | Three layers, built in: builder access, agent permissions, execution control |
| Audit trail | Custom logging, built to your own standard | Every action, agent or human, same immutable trail |
| Secrets management | Integrate and maintain your own vault connections | Runtime injection from Vault, CyberArk, AWS Secrets Manager, or Azure Key Vault |
| Rollback on failed execution | Tested only against incidents your team has already hit | Pre/post validation proven across a decade of production incidents |
| Multi-vendor integrations | Build and maintain your own adapters | 1,000+ pre-built, open source, community maintained |
| Time to production-grade | Months to years, and it’s now your product to maintain | Already done; the work left is building agents, not the platform under them |
Either way, building this internally means owning a new product from day one, with its own bugs, its own maintenance, and its own liability. Adopting FlowAI means starting from a decade of that work already done.
A model reasons. A harness decides what it’s allowed to do with that reasoning. FlowAI is that harness for the Itential Platform: Tools, Skills, Context, and Governance, running on the same engine and under the same audit trail as every deterministic workflow already running today. It works with any model. It doesn’t require rewriting existing automation. It doesn’t require adopting agents before a team is ready.
That governance isn’t new. It’s the same RBAC, audit, and rollback discipline proven across more than a decade of production use, at a scale most teams building their own harness will never test against before they have to.
Most agent harnesses were built for coding tools, where a mistake gets caught in a pull request. Infrastructure doesn’t get that safety net. FlowAI was built for the environment that doesn’t forgive mistakes: real devices, real production traffic, real audits. That’s not a smaller version of the same problem coding harnesses solve. It’s a different one. And it’s the one Itential has spent a decade already solving.

A workflow is deterministic: a defined sequence of steps with validation, approval gates, and rollback built in. It executes exactly as built, every time. A FlowAgent is the reasoning layer above workflows: it interprets a goal, queries infrastructure state, selects the right workflows as tools, and sequences them based on what it finds. Agents adapt. Workflows execute predictably. Most teams use both.
LangChain and LangGraph build agent reasoning logic well, but leave the execution layer entirely to the team building on them: API wrappers, secrets management, RBAC, audit logging, rollback, and approval gates all become custom code owned in production. FlowAI provides the execution layer those frameworks don’t. Agents can reason in any framework and execute through Itential, with every action carrying pre- and post-validation, RBAC enforcement, and a complete audit trail without building that infrastructure from scratch.
Assistants like Copilot surface recommendations. They don’t execute infrastructure changes. An assistant can suggest a remediation; it can’t validate pre-conditions across a device estate, execute a governed workflow, confirm post-change state, and produce an immutable audit trail within defined approval thresholds. FlowAI closes that gap, and assistants like Copilot can connect to Itential via MCP: the assistant reasons, Itential executes.
Yes. Existing playbooks, scripts, and plans become callable tools that FlowAgents can reason over and invoke. Engineers keep building in the tools they already use. The platform handles execution, RBAC, audit logging, and rollback for every call, whether the trigger is an agent, a workflow, or a person.
Both, configured per agent and per operation. Autonomy thresholds are set in FlowAgent Builder: fully autonomous for low-risk operations below a defined threshold, human-in-the-loop for operations requiring explicit approval, or human-on-the-loop for monitored execution without per-step approval. An agent cannot self-escalate beyond what was defined when it was built.
No. A FlowAgent reasons over a fixed set of tools, but it never holds, sees, or handles a credential directly. Every credential lives where it always has: on the Integration Instance, Adapter, or Itential Gateway service the agent is authorized to call, injected at execution time only. A builder can scope an agent to a read-only or narrowly permissioned integration instance, so the agent’s blast radius is bounded by that instance’s access, not by anything the agent carries. The agent reasons. The credential stays in custody.
Yes. A FlowAgent can invoke another agent or a workflow as part of its reasoning, and FlowAgent Sessions record the full chain: every reasoning step, every tool call, and any child sessions the agent triggered. Visibility works the same way whether the agent called a workflow, another agent, or an external MCP tool.
Yes, FlowAgents can and should be scoped to a staging or non-production integration instance during development, so reasoning and tool selection can be validated before an agent is given access to production systems.
No, and the difference isn’t the reasoning loop, both plan, call tools, and loop on results. It’s the operating conditions. A coding harness runs with a developer supervising every turn, inside a repo and a sandbox where mistakes are cheap to undo. A FlowAgent runs unattended, triggered by a workflow or an API call, acting on live infrastructure where changes are real. A coding harness doesn’t need a fixed tool registry or a bounded blast radius because a human is watching every step and a sandbox contains the damage. A FlowAgent has neither safety net by default, so the platform provides one instead.
An agent harness = model + tools + skills + context + governance + the loop that keeps it working. The model is only one piece of that. Swap the model and the harness stays the same, the RBAC, the tool scope, and the audit trail don’t change based on which LLM is plugged in. When people equate this to what they already do in Claude or ChatGPT, they’re usually picturing the chat interface plus the model, not a system that scopes and governs what an agent can do before it ever runs. See the FlowAgent vs. chat assistant and coding harness comparison above for exactly where that difference shows up in practice.
See how Itential connects AI reasoning to governed execution across your entire infrastructure.